 Assemblage, Expédition et Support de toutes les commandes depuis l'Union Européenne
High-Performance Shared Storage for AI, Analytics and Production Workloads
Broadberry WEKA storage combines NVMe performance with a distributed filesystem designed for demanding shared workloads. Each solution is tailored to your workload, active dataset, concurrency, performance and capacity requirements.

WEKA distributes file data and metadata across storage backends, allowing many clients to access shared files without relying on a single intermediary server.
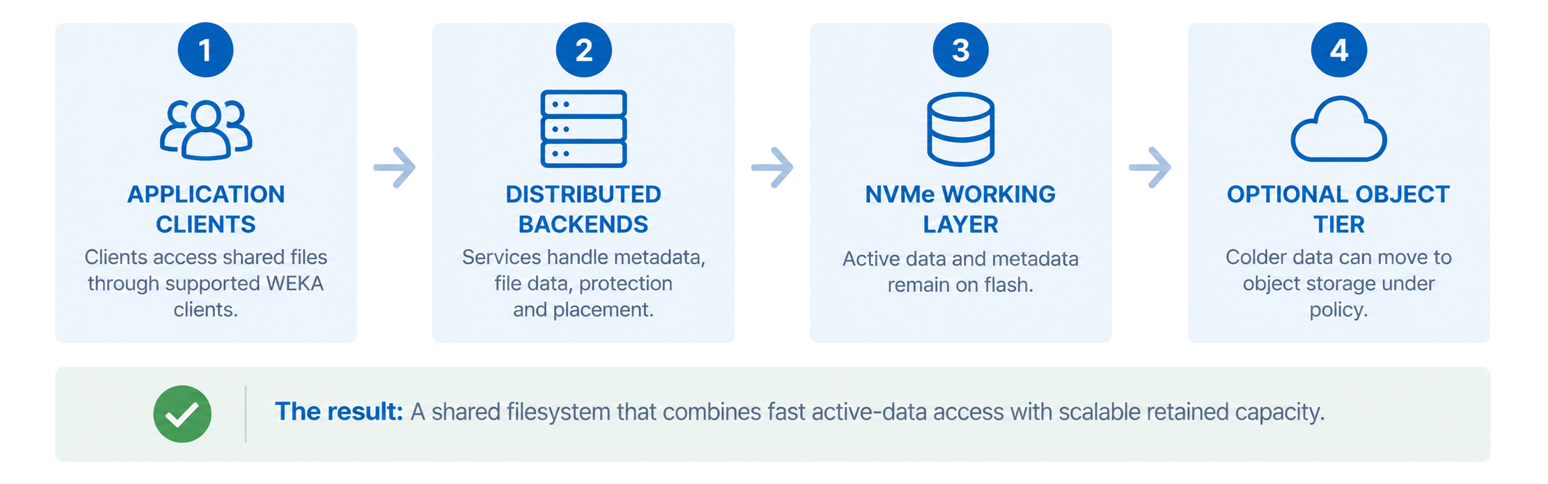
Before recommending a WEKA architecture, Broadberry evaluates your active dataset, concurrency, client resources, performance targets and retention requirements.
Model file sizes, concurrency,
throughput and metadata
activity.
Size active flash, retained
data, protection reserve and
growth.
Choose dedicated or tiered
WEKA deployment
models.
Engineer CPU, memory,
NVMe, networking and client
resources.
Test application
performance, tiered reads,
failover and recovery.
Plan expansion, software
support, upgrades and
ongoing operations.
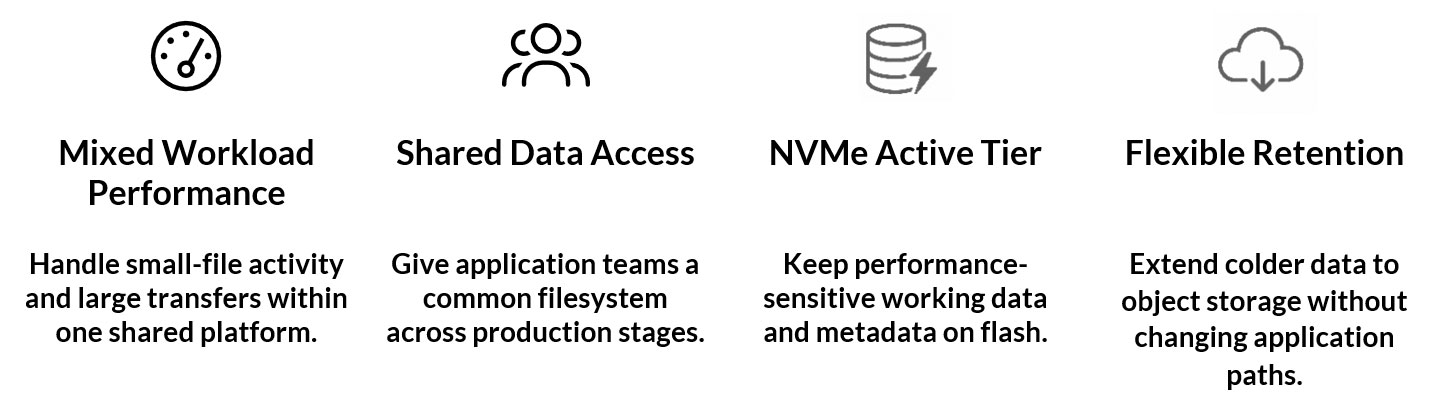
WEKA is best suited to applications where file I/O is a measured performance constraint. Broadberry sizes the platform around the actual mixed workload rather than a single synthetic bandwidth number.
| Workload | Typical I/O | Design Priority |
| AI Training & Fine-Tuning | Shared reads, small-file access, checkpoints | Active-data performance and concurrency |
| Engineering & Builds | Frequent opens, creates and small-file reads | Metadata rate and client resources |
| Media & Rendering | Parallel asset reads and output streams | Sustained bandwidth and mixed I/O |
| Life Sciences & Research | Shared inputs and varied intermediate files | Working-set capacity and concurrency |
| Analytics & Data Processing | Repeated access to shared datasets | Throughput and application response |
| Retained Projects | Occasional access to colder data | Object retrieval and flash residency |
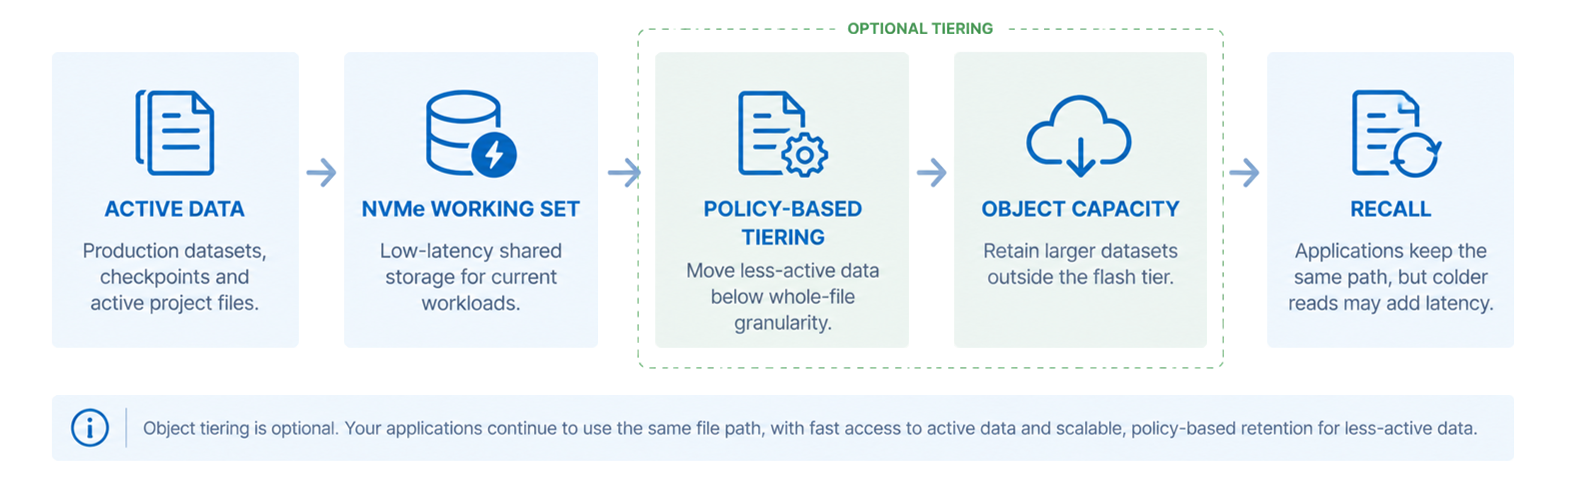
WEKA is well suited to performance-sensitive shared workloads that combine metadata activity, concurrency and large data transfers.
| Use Case | Typical Requirements |
| AI & Machine Learning | Shared training data, concurrent reads and checkpoint writes |
| Engineering & EDA | Small-file activity, builds and metadata-intensive workflows |
| Media & Visual Effects | Parallel asset access and large output streams |
| Life Sciences | Shared project data and mixed intermediate files |
| Financial Analytics | Repeated dataset access and low-latency processing |
| Scientific Computing | High-concurrency analysis with active data on flash |
| WEKA Is a Strong Fit When... | Consider Another Approach When... |
| Shared workloads are latency- or metadata-sensitive | Storage is primarily capacity-only archive |
| Applications need concurrent access to active datasets | Simple office file sharing is the main requirement |
| NVMe performance is important | HDD economics matter more than active-data performance |
| Workloads benefit from shared flash plus object retention | Software licensing simplicity is a primary goal |
| AI, analytics, engineering or media workloads dominate | File I/O is not the actual application bottleneck |
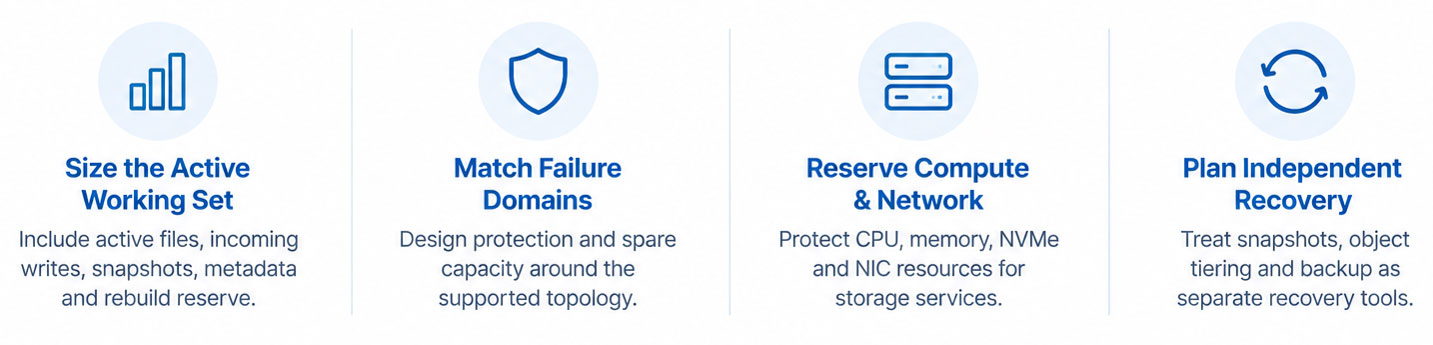
Broadberry combines WEKA software expertise with workload-led hardware design to deliver a qualified storage platform built around the way your applications actually use data.

Architecture based on active datasets, concurrency and performance requirements.

NVMe, CPU, memory and networking selected around WEKA support requirements.

Storage, client resources, networking and lifecycle policies designed together.

Qualification, validation, expansion and ongoing operational support.
Which workloads benefit most from WEKA?
WEKA is best suited to shared applications with demanding latency, metadata or throughput requirements, including AI, engineering, media, scientific processing and analytics.
Is an external object store required?
No. A WEKA configuration can keep all data on flash. Object storage is optional and can be used for additional capacity or recovery.
Does tiering change the application's file path?
No. Applications continue to use the same logical file path while WEKA manages data placement. Reads from data held only in the object tier may have additional latency.
Is WEKA suitable for AI and GPU clusters?
Yes. WEKA can provide shared NVMe storage for concurrent training reads, metadata-heavy pipelines and checkpoint workloads. The full application pipeline should be validated before scaling.
Does GPUDirect Storage make every AI application faster?
No. GPUDirect Storage can reduce CPU-memory copies on supported paths, but the application must use an enabled configuration. Other bottlenecks can limit performance, so the complete pipeline should be tested.
Can WEKA run alongside application compute?
Yes. WEKA supports converged and dedicated deployment models. Resource budgets for CPU, memory, devices and networking must be reserved appropriately when roles are combined.
Does distributed protection replace backup?
No. Local snapshots and fault-tolerant storage protect against different risks than independent backup and disaster recovery.
Will tiered data always respond at NVMe speed?
No. Data resident on flash uses the SSD path, while reads of object-only data require retrieval from the capacity tier.
Tell us about your applications, active dataset, concurrency, performance targets and retention requirements. Broadberry will design a WEKA hardware platform around the flash capacity, client resources, networking and lifecycle model your environment needs.
Speak with a Storage Expert
 Notre Procédure de Tests rigoureuse
Avant de quitter nos ateliers, toutes les solutions de serveur et de stockage Broadberry sont soumises à une procédure de test rigoureuse de 48 heures. Ceci, associé à un choix de composants de haute qualité, garantit que toutes nos serveurs et solutions de stockage répondent aux normes de qualité les plus strictes qui nous sont imposées.
 Une Flexibilité Inégalée
Notre principal objectif est d'offrir des serveurs et des solutions de stockage de la plus haute qualité. Nous comprenons que chaque entreprise a des exigences différentes et sommes en mesure d'offrir une flexibilité inégalée dans la personnalisation et la conception de serveurs et de solutions de stockage.
Nous nous sommes imposés comme un incontournable fournisseur de stockage en Europe et fournissons depuis 1989 nos solutions de serveurs et de stockage aux plus grandes marques mondiales. Quelques exemples de clients :
impressum / returns / Mon compte / Contactez-nous / new accounts
CyberServe EPYC EP1-102A
A powerful AMD EPYC rack server for small spaces...
| August 26, 2026
CyberServe Ryzen RY1-104A
A core-heavy Ryzen rack server at an entry-level price ...
| April 01, 2024
CyberServe Xeon SP1-102G NVMe G5
A small, powerful, and affordable rack server.
Broadberry gets edgy with a great value rack server...
| December 01, 2023
Intel M50CYP2UR208 Coyote Pass Server - 8 Drive Bays. SAS/SATA/NVME
A mighty server package for the price with a big helping of blisteringly fast Intel Optane 200 PMEMs...
| August 02, 2021
 Appelez notre équipe commerciale française maintenant
